OpenAI used LLMs to design its Jalapeño chip. Hardware engineering just entered the AI era.
OpenAI applied large language models to physical chip design, proving AI can solve concrete engineering problems beyond code. The project demonstrates LLMs tackling real-world hardware constraints and optimization.
September 19, 2026
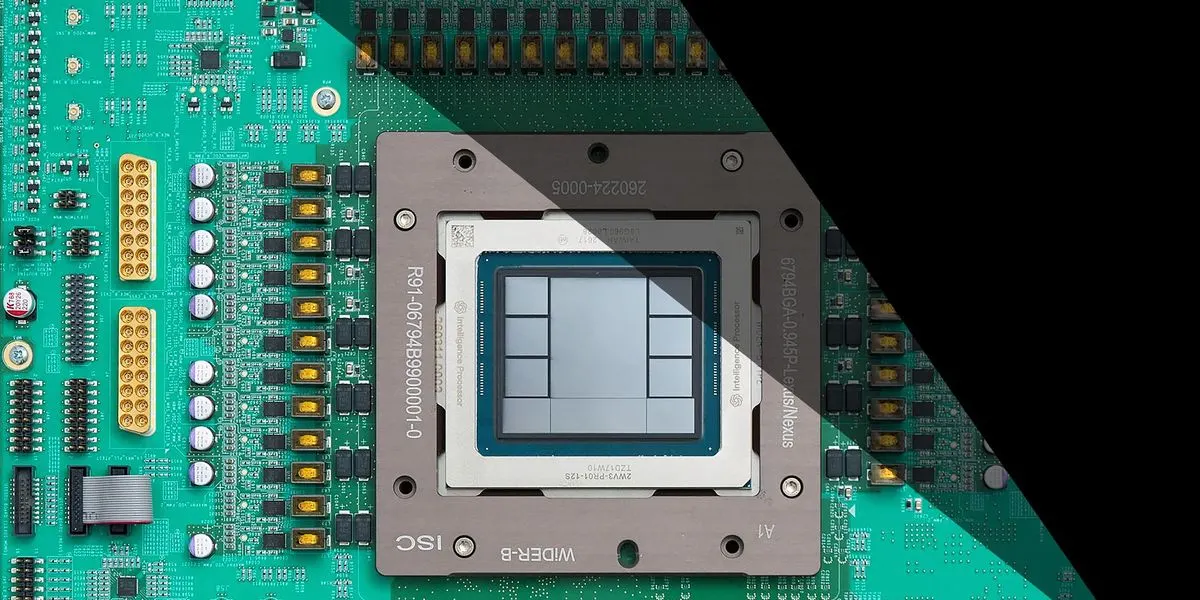
The IEEE Spectrum piece opens on a whiteboard full of RTL diagrams and a hardware engineer pulling up a chat window next to a Verilog file. That image is the whole story in miniature: a chip designer treating a language model the way a software engineer treats an autocomplete tool, except the code it is suggesting controls transistors instead of API calls. According to the report, OpenAI used its own models to help design a chip internally referred to as Jalapeño, applying LLMs to register-transfer-level code, testbenches, and the kind of verification work that normally eats months of an engineering calendar.
That detail matters more than the chip itself. Chips get taped out every quarter. What is rarer is a frontier AI lab publicly walking through how it used its own product to solve a problem that has nothing to do with chatbots, coding assistants, or content generation. Hardware design is slow, expensive, and famously intolerant of mistakes. If a model can meaningfully help there, that is a different kind of proof than another benchmark score.
A hardware engineer and a skeptic argue about it
Skeptic: Chip design has formal verification tools that have existed for decades. What does a language model add that Cadence and Synopsys don't already do?
Engineer: Speed on the first draft. Writing a testbench from a spec document used to take a day. Now I get a starting point in minutes and spend the day reviewing it instead of typing it.
Skeptic: Reviewing generated RTL sounds worse than writing it. One wrong bit in a control path and you've burned a mask set worth millions.
Engineer: Nobody taped anything out on the model's word alone. The LLM output still goes through the same simulation and formal checks every other line of RTL goes through. The gain isn't trust, it's throughput on the boring 80 percent.
Skeptic: Then call it a faster typist, not a chip designer.
Engineer: Fine by me. A faster typist who never gets tired at 2am before tape-out is still worth having.
Why RTL Is a Better Fit for LLMs Than It First Appears
The obvious objection to using language models for chip design is that hardware is unforgiving in a way software is not. A bad software deploy gets rolled back. A bad chip design gets fabricated, and you find out twelve weeks later when the silicon comes back from the foundry broken. That asymmetry is real, but it is also exactly why the mechanism here works better than skeptics expect. Verilog and VHDL are text. They compile, simulate, and produce pass/fail results against a testbench, which means every RTL change already lives inside a tight feedback loop, the same kind of loop that makes coding agents like Claude Code or GitHub Copilot useful for software. The difference with hardware is that the feedback is stricter. A testbench either catches the bug in simulation or it doesn't, and teams that do this work have spent decades building verification suites precisely because they don't trust any single engineer's first draft, human or machine. That is the part the headline undersells. The story is not "AI designs a chip." It is "a domain with rigorous, automatable verification turns out to be one of the safest places to let a language model write structural code," because the safety net was already built for humans who make mistakes too. The lesson generalizes past chips: wherever a strict, automated check already exists, LLM-generated output is verified before anyone commits to it. Wherever that check doesn't exist, and this is the case for a lot of software glue code, LLM output is a much riskier bet.
How to try an LLM-assisted RTL workflow without betting a tape-out on it
- Pick a small, well-defined block, something like a UART controller or a FIFO buffer, that already has a written spec and an existing testbench you trust.
- Write the spec as plain-language requirements first, not code. Feed it to a coding-capable model such as Claude or ChatGPT and ask for a first-draft Verilog module against that spec.
- Run the generated module through your existing simulator immediately. Do not read the code first and judge it by eye. Let the testbench decide.
iverilog -o sim_out testbench.v generated_module.v vvp sim_out - Log every failing assertion. Feed the failure output back to the model along with the relevant signal names and ask it to correct only the failing behavior, not rewrite the whole module.
- Repeat the simulate-fix loop until the testbench passes clean, then hand the result to a human reviewer who has never seen the AI's intermediate drafts, so the review is not anchored by prior context.
- Run a formal equivalence check between the human-approved version and a hand-written reference implementation of the same block before it goes anywhere near synthesis.
Verification test: if the AI-assisted module passes the same regression suite as a block written entirely by hand, with zero new bugs introduced across three independent simulation runs, the workflow earned its place. If you find yourself skipping the formal equivalence step because the deadline is close, that's the moment the process has already failed.
Why One Internal Project at OpenAI Isn't Proof This Scales
Here is the argument nobody wants to make out loud: one internal chip project at one company is not evidence that LLMs are ready for hardware design, and treating it that way flatters OpenAI's narrative more than it informs anyone's roadmap. Jalapeño, per the reporting, is OpenAI using its own models on its own hardware team with its own engineers reviewing every output, which is the single most controlled environment imaginable. That is nothing like a fabless startup with three RTL engineers betting a Series A on an AI-assisted tape-out with no formal verification bench and no time to build one. Chip design failures are also asymmetric in a way that punishes overconfidence specifically. A bad software bug ships a patch. A bad hardware bug ships a recall, or worse, ships silently and shows up as a field failure two years later in a product nobody can update remotely. The entire discipline of hardware verification exists because humans already get this wrong constantly, and the fix has never been "write the RTL faster." It has been "trust the RTL less and verify it more." An LLM that writes a first draft faster does nothing to change how much verification a safety-critical block needs. If anything, faster first drafts without a proportional increase in verification rigor is exactly the failure mode chip teams have spent forty years engineering against. None of that means the IEEE Spectrum report is wrong about what OpenAI did internally. It means the leap from "this helped one team on one project" to "LLMs are now solving real-world engineering problems" is doing a lot of unearned work. The interesting claim isn't that a model can draft Verilog. It's whether the verification discipline required to trust that Verilog scales to teams without OpenAI's headcount and budget.
Verification checklist before you take any of this at face value
- Confirm whether the source report describes AI-assisted drafting with human sign-off, or actual autonomous design decisions, before repeating either claim as fact
- Check whether any AI-generated RTL in your own workflow passed the exact same regression and formal-equivalence checks as human-written code, not a lighter version
- Verify that model-generated testbenches are being reviewed by someone who did not write the prompt, to avoid anchoring bias in review
- Look for whether OpenAI or the reporting names specific verification tooling used alongside the LLM, and treat unverified claims about "LLM-designed" hardware as marketing shorthand until they do
- Re-read the original IEEE Spectrum report for what it actually attributes to OpenAI versus what got compressed in the retelling
For more on where LLM claims tend to outrun what the evidence actually supports, see our breakdown of separating LLM hype from reality, and if you're evaluating coding-capable models for your own verification-heavy workflow, this comparison of Cursor and GitHub Copilot is a reasonable starting point even outside software.
Tools mentioned in this article
Some links in this article are affiliate links. Learn more.