How-To Guides
19 articles
Runway's Unlimited plan ends November 30. Here is what to do before then.
Runway is replacing Unlimited and its relaxed Explore Mode with a credit-capped Max plan at the same $95 a month. What you lose, what each Runway plan buys now, and when switching to Pro or another video tool makes sense.
Free Gemini drops to Flash Lite on October 9. Free users have better options now.
From October 9, free Gemini app users lose Flash and Pro and keep only Flash Lite. Here is exactly what changes on each plan, what stays free for developers, and where to go if you want a capable AI assistant without paying.
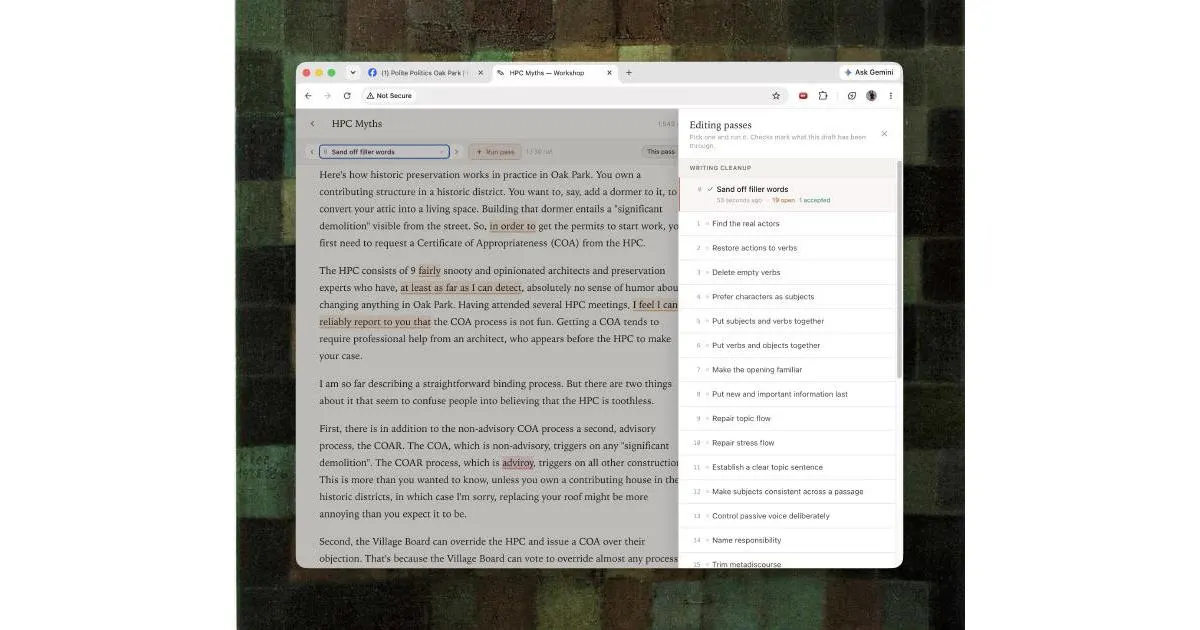
Writing with LLMs: A practical guide to better AI-assisted composition
A comprehensive guide on effective writing techniques when using large language models, covering strategies to improve output quality and maintain authentic voice in AI-assisted writing.
GPT-5.6 Luna vs GPT-6 Astra. A $1.20 model catches 75% of bugs.
A Reddit benchmark tested two models on 50 real pull requests. Astra found more bugs overall, but Luna achieved 75% of its accuracy at just 3.6% of the cost.
AI Workflows Promise Automation. Reality Demands Expertise.
A Reddit discussion surfaces a persistent pain point: multi-agent AI systems look seamless in demos but demand significant setup complexity in practice. Users question whether the operational burden outweighs actual productivity gains.
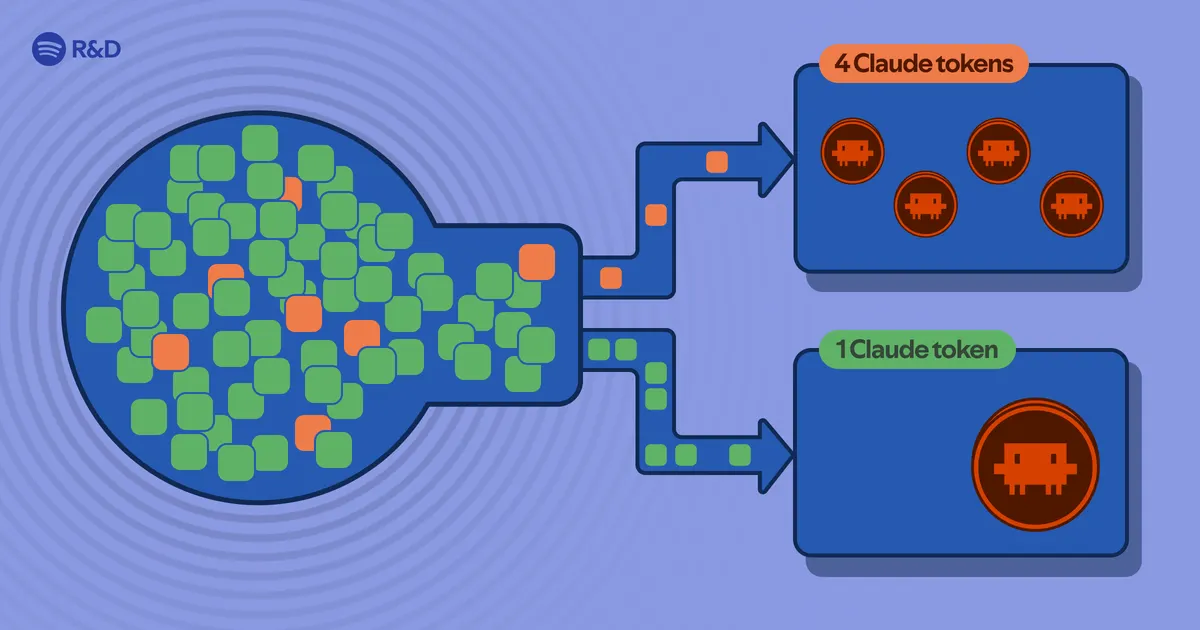
Spotify's Portal slashed Claude Code tokens by 90%. Here's how.
Spotify engineering published a case study showing Portal, their internal tool, reduced Claude Code token consumption dramatically. The real performance metrics reveal significant cost implications for organizations using AI coding assistants.
Claude gets system prompts. Developers can now shape model behavior at scale.
Anthropic released a system prompts feature for Claude, allowing developers to define consistent behavior patterns across API calls without prompt engineering for each interaction.
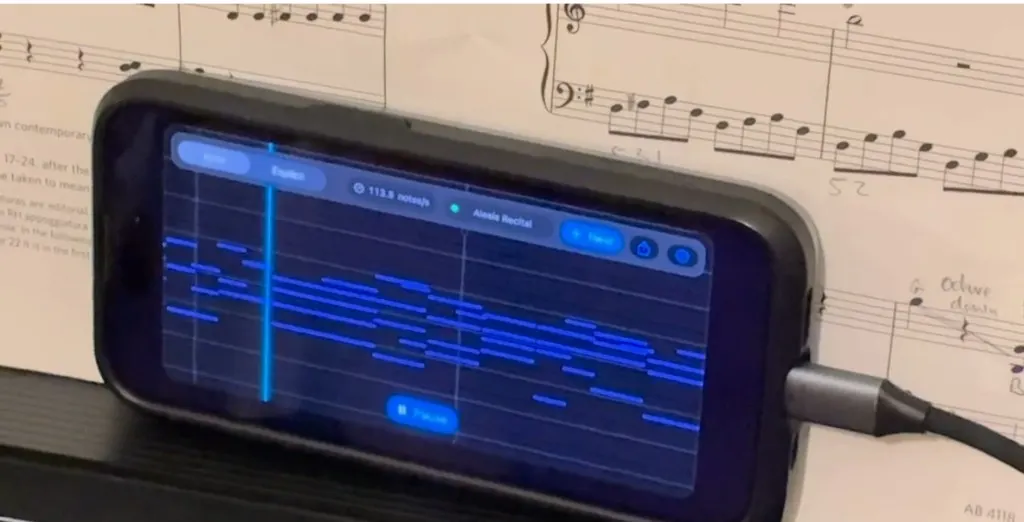
Developer trains 125M model for piano autocomplete. It runs on-device at 108 notes per second.
A transformer-based MIDI autocomplete system brings Copilot-style assistance to piano performers, running efficiently on iPhone 15 with real-time inference. The 125M-parameter model demonstrates how code completion patterns can translate to musical performance.
LLMs as learning tools. A developer shares his technique for mastering difficult subjects.
A practical guide on using large language models to break down and understand complex topics, with strategies for deeper learning beyond surface-level answers.
Retyping LLM code manually. The friction builds understanding.
A developer argues that manually retyping code generated by AI tools like Claude and ChatGPT prevents cognitive debt by forcing deeper engagement with the code logic rather than mindlessly accepting suggestions.
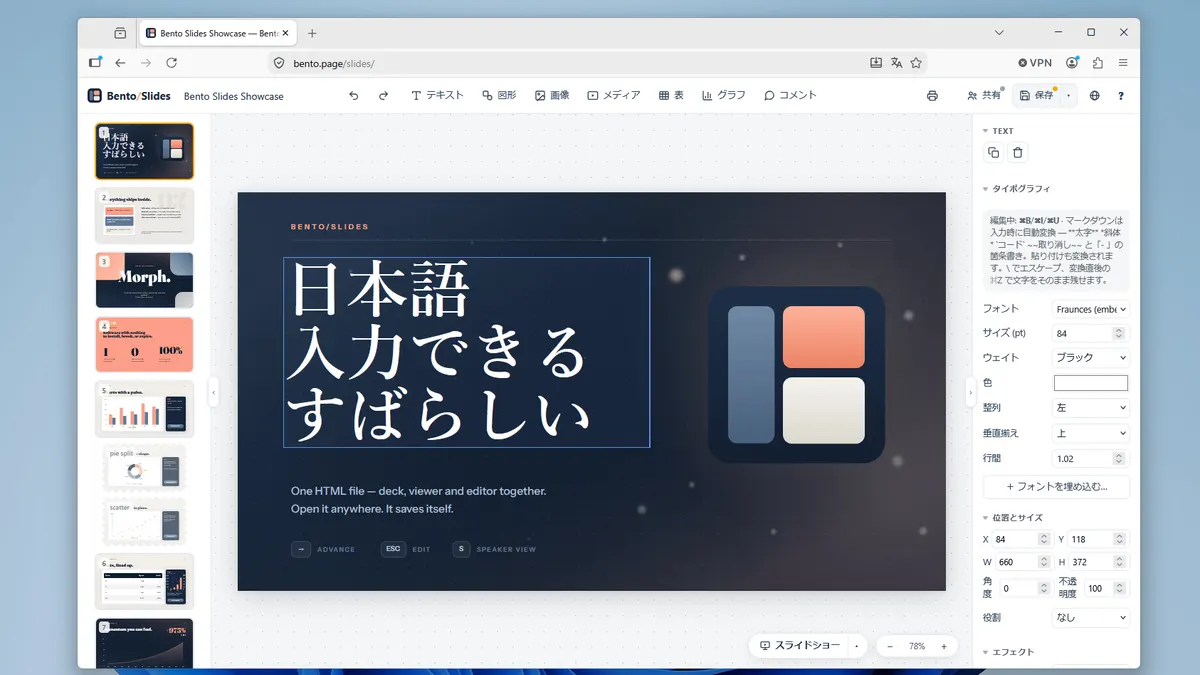
Bento turns PowerPoint into one shareable HTML file. Edit, view, and collaborate without leaving the browser.
Bento is a web-based presentation tool that packages entire slideshows into single HTML files, integrating with Claude Code for AI-assisted editing and real-time collaboration without manual code intervention.
Claude has a verbal tic. Here's how to fix it.
A developer discovered that Claude frequently overuses the phrase "load-bearing" in responses. A practical prompting technique can eliminate this quirk and improve output quality.
Run state-of-the-art LLMs locally. Jamesob's guide shows what it takes to drop the cloud.
A popular GitHub guide documents local LLM builds from a roughly $2,000 two-GPU setup to a $40,000 four-GPU workstation. When local inference pays off, how local stacks fail, and how current API prices change the math.
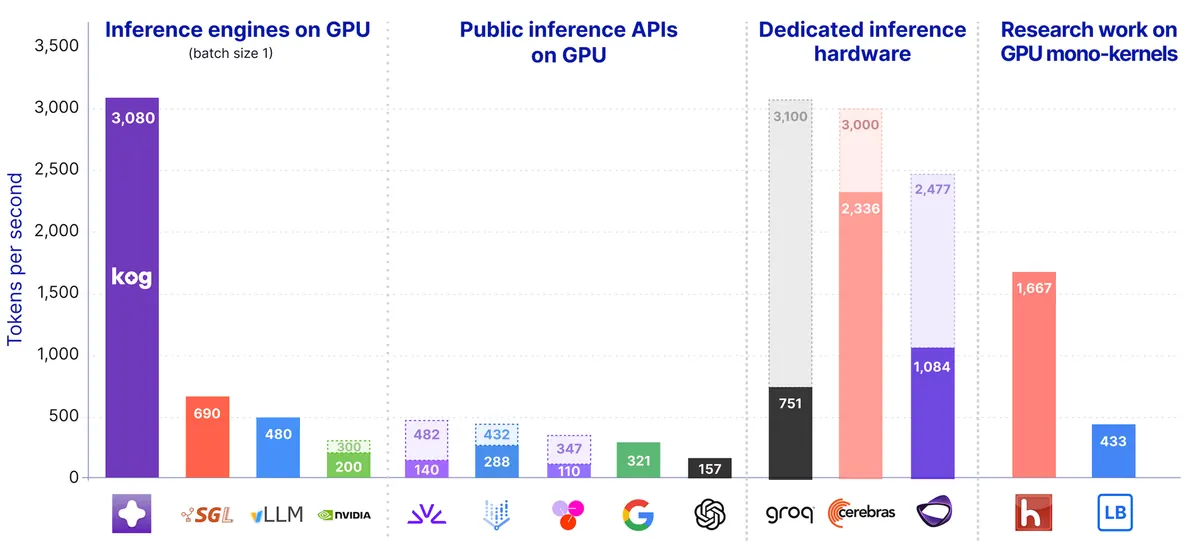
Kog reports 3,000 tokens/sec LLM inference per request on standard GPUs
Paris startup Kog says its inference engine generates 3,000 output tokens per second for a single request on one 8-GPU AMD MI300X server, using its own 2B-parameter model. What the number covers, what it leaves out, and how to judge claims like it against your own setup.
Using AI to Write Better Code More Slowly
A developer explores how AI coding assistants can improve code quality when used thoughtfully, even if they slow down the writing process initially.
Forge Boosts Local Model Agentic Task Accuracy to 99%
Forge is an open-source reliability layer that adds guardrails to self-hosted LLM tool-calling, improving an 8B model's performance from 53% to 99% on agentic tasks through retry logic, error recovery, and context management.
EvanFlow: TDD Feedback Loop for Claude Code
Open-source tool EvanFlow creates a test-driven development feedback loop optimized for Claude Code, helping developers improve code quality and accelerate iteration cycles.
CodeBurn: Monitor Claude Code Token Spending by Task
New open-source tool gives developers granular visibility into token consumption across Claude Code agents, solving cost tracking problems for teams spending $1400+ weekly on AI-powered coding.
Run Gemma 4 Locally with LM Studio's CLI
LM Studio's lms CLI serves Gemma 4 on localhost through OpenAI- and Anthropic-compatible endpoints, so Claude Code and Goose can run against a model on your own machine with no per-token cost and no prompts sent to a cloud model.